Showing posts with label lexical complexity. Show all posts

Tuesday, January 28, 2014

XKCD and simplification.

I have been an avid reader of the webcomic xkcd since my days as an undergrad.  If you've never heard of it, I would recommend you check it out, some of them are laugh-out-loud funny.  There are several comics that stick out as having a simplification theme.  I'm going to use this post to look at those comics through the lens of automatic simplification.  I'll try to explain what we can do with the current technology and what we just plain can't.

Simple

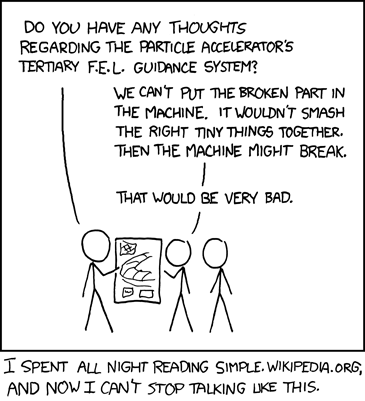
Particle accelerators are complex beasts.  I can empathise with the character who read so much simple Wikipedia that he can only talk in that way now.  One of the techniques we use in simplification is language modelling.  A mathematical model of sentences is trained which can be used to score new sentences to say how likely they are to have been produced by a language.  So for example:  "I went to the bank" might recieve a higher score than "I to the banking place did go".  As the latter sentence is poorly written.  An interesting factor of language models is that the scores they give rely heavily on the sentences which are used to train them.  So if you train a model using the text of the English Wikipedia you are likely to get very difficult to understand language.  If you train a model using the text of Simple Wikipedia, you are likely to get very simple sounding language, just like the second character in this comic.  A great paper which explains this further (without the xkcd references) is Kauchak (2013) (see the lexical simplification list).

Up Goer Five

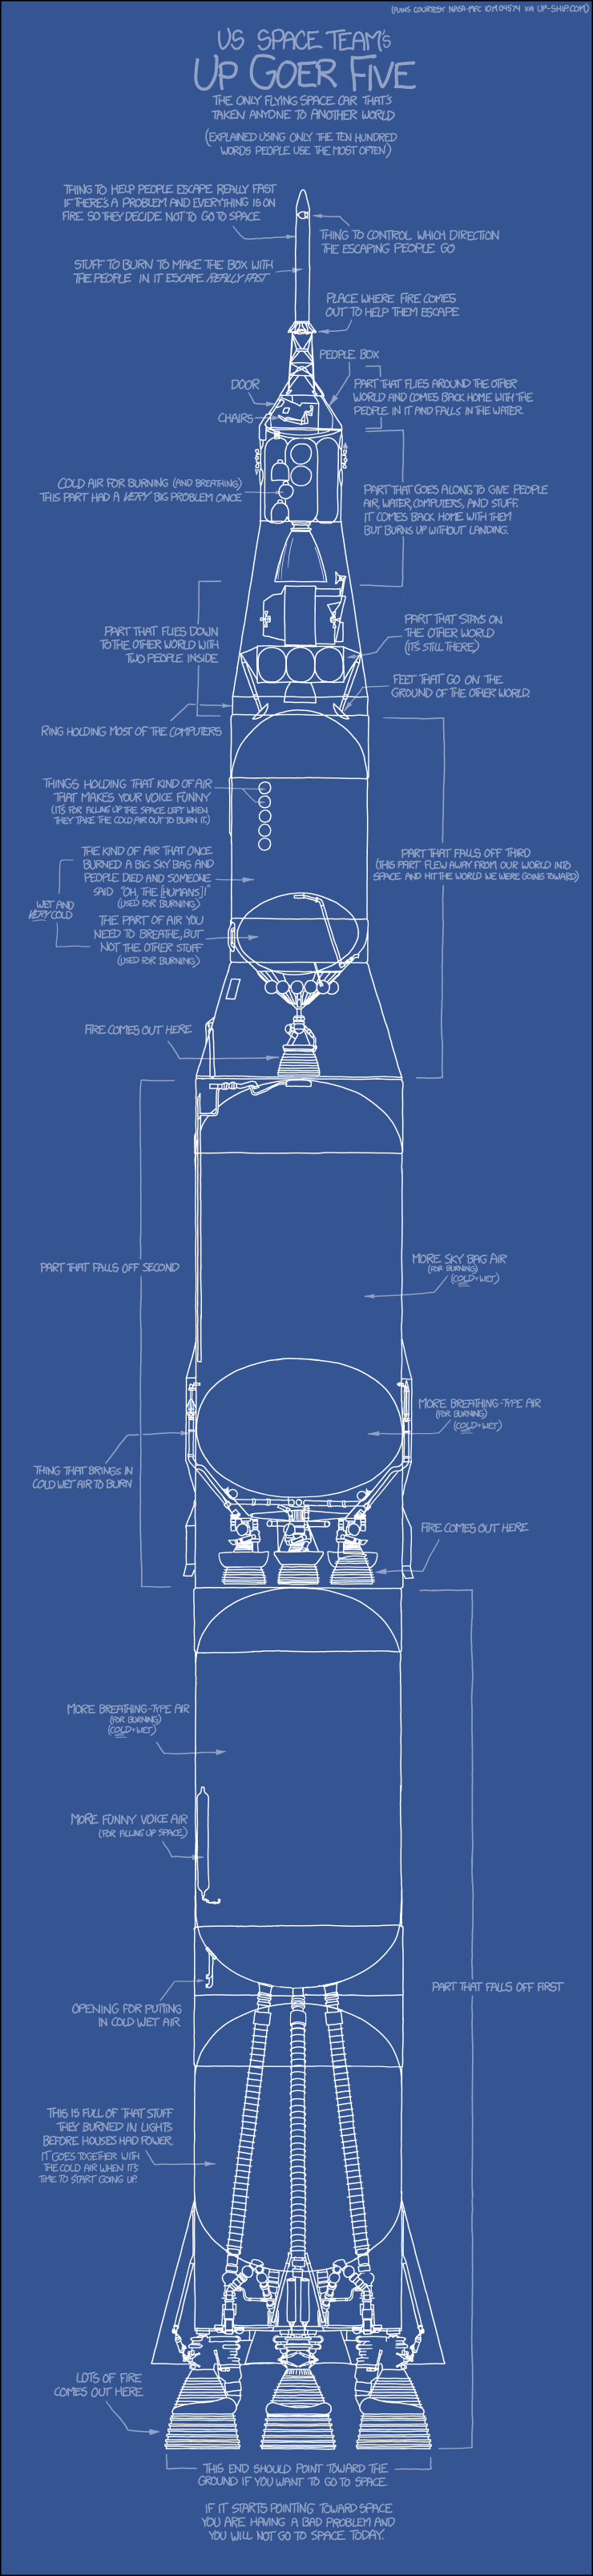
This next one is too long to put in this post - but it's worth a read.  The full comic is here: Up Goer Five (Or, right click on the image and open it in a new tab to view).

The comic presents a simplified blueprint of the Saturn V rocket.  The translator has been restricted to only the thousand most common words in the English language.  There is some question as to where the statistics for the 'thousand most common words' came from.  If it were taken from NASA technical rocket manuals then there may have needed to be little change!  We'll assume that it was taken from some comprehensive resource.  The best way of determining this with currently available resources would be to use the top ranked words in the Google Web1T corpus (Google counted a trillion words and recorded how often each one occurred.)

The style of translation in this comic is phenomenally difficult to achieve, even for humans.  You can try it for yourself at The Up-Goer Five text editor.  Most words have been substituted for simpler phrases, or explanations.  Some technical terms rely on outside knowledge - which actually has the effect of making the sentence more difficult to understand.  For example, one label reads: "This is full of that stuff they burned in lights before houses had power".  This is referring to kerosene, which is highly understandable if you know of kerosene but inapproachable if not.

It would be an interesting experiment to determine the lowest number of words required to be able to produce this kind of simplification without having to draw on inferred knowledge (such as the type of fuel lights once burned).  My guess is that you would need 10 - 20,000 before this became a reality.  It would be difficult to automatically produce text at this level of simplicity.  Explaining a concept requires a really deep understanding and background knowledge, which is difficult to emulate with a machine.

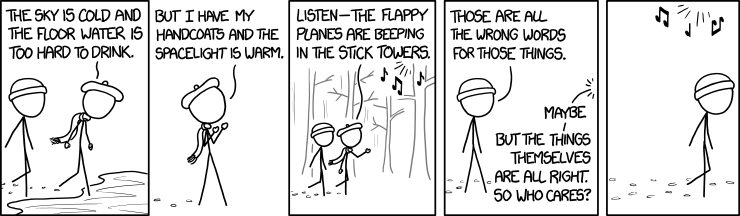
Winter


The above comic touches on an excellent point.  If the words we use are understandable, does it matter if they're not the correct words? Previously, I have written about lexical complexity noting that many factors affect how difficult we find a word.  The big factor that is played on here is context.  For example the term 'handcoats' in the second panel is understandable (as gloves) because we know from the first panel that 'the sky is cold'.  Handcoats is a word that you've probably never seen before, and out of context it would be difficult to get the meaning.  This highlights the importance of selecting words which fit the context of a sentence. If the correct context is chosen and a simple word fitting that context is used, then the understandability of a sentence will be dramatically increased.


Friday, September 06, 2013

3rd Year

On Wednesday (4/9/2013) I successfully completed my end of second year interview.  This means that I am now officially a third year PhD student.  I am now at the dead halfway point of my PhD, having completed 24 months with 24 more remaining.  It has been a long road getting here and there is still a long way to go.  Below is a brief analysis of the achievements in my PhD so far and the goals yet to come.


Completed So Far:

  • Literature Review:  This was the first thing I did as a PhD student.  Reading took up most of the first six months of my research.  I consumed, refined and categorised as much of the relevant literature as I could find.  I am attempting to publish this as a survey paper currently, since the only available text simplification survey is a technical report from 2008
  • Lexical Simplification Errors: I recently undertook a pilot study looking at the errors thrown up by the lexical simplification pipeline.  I'm looking to publish this in an upcoming conference, so won't say too much about the results here and now.
  • Complex Word Identification: This was the first element of the lexical simplification pipeline that I studied.  I built a corpus of sentences, each with one word marked as complex for the purpose of evaluating current methods of identification.  This work was published in 2 separate workshop papers at ACL 2013.
  • Substitution Generation: Once we have identified a complex word, we must generate a set of substitutions for it.  However, those words which are complex are also those which are least likely to be found in a thesaurus, complicating the task.  To address this I spent considerable efforts learning simplifications from massive corpora with some success.  This work is also currently being written up for publication.


Still to come:

  • Word Sense Disambiguation: The next step in the pipeline is to apply some word sense disambiguation.  This has been done before, so I will be looking at the best ways to apply it and hopefully making a novel contribution here.  I am just starting out on this phase of research and am currently immersed in the WSD literature, trying to get my head round the myriad techniques that already exist there.
  • Synonym Ranking: I have looked into the best way to rank synonyms according to their complexity before at the start of my project.  The small amounts of work that I did back then did not discover anything radical, but did help me to better understand the structure of a lexical simplification system.  When I revisit this area it will be with the hope of making some significant contribution.  I was really interested in the work David Kauchak presented at ACL 2013 and will be interested to explore what more can be done in this area.
  • User Evaluation: Finally, I will spend some time exploring the effects of each of the modules I have developed on individual users.  It is of paramount importance to evaluate text simplification in the context of the users it is aimed at and to this end I will be focussing my research on a specific user group.  Although which group is as yet undecided.
  • Thesis: This will undoubtedly take a significant portion of my final year.  The chapter titles will hopefully be the bullet points you see listed above.

So there you have it.  Although it appears that I have done a lot so far, it still feels like I have a real mountain to climb.  There are significant hurdles and vast amounts of reading, researching and writing ahead.  I look forward to the challenges that the next two years of my PhD will bring.

    Thursday, August 15, 2013

    Orthography, Phonology and Nomenclature. Making sense of word relations!

    In my role as computational linguist, I often find myself verging into areas of linguistics which I find nothing short of fascinating.  One such is the complex relation between English orthography (that is, how a word is written) and phonology (how it sounds).  In English, we have a 'deep orthography' meaning that a word doesn't necessarily sound the way it looks, leading to beautiful confusions such as:
    weight vs. height

    foot vs. food
    or (my favourite):
    cough vs. enough vs. plough vs. though. vs. through.
    That's right, 5 distinct sounds from the letters 'ough'.

    We also get the interesting phenomenon that one set of letters, with different pronunciations can have totally different meanings.  For example.
    He decided to desert the army.
    Camels live in the desert.

    This is an example of heteronyms.  Heteronyms are different to homonyms which have the same pronounciation and spelling, but a different meaning. These are different again to heterographs, homophones and synonyms.  The table below defines the potential relations between words.  It is taken mostly from this venn diagram

    Meaning Spelling Pronunciation
    No Relation Different Different Different
    Homophone Different - Same
    Heterograph Different Different Same
    Heteronym Different Same Different
    Homonym Different Same Same
    Different Spelling Same Different Same
    Different Pronunciation Same Same Different
    Synonym Same Different Different
    Same Word Same Same Same

    • No relation: Two word words which are not related in any sense.
    • Homophones:  Words which sound the same, but have different meanings.  Further split into the following two categories:
    • Heterographs: Homophones with different spellings.  "There", "Their" and "They're" is a classic example.
    • Homonyms: Homophones with the same spelling.  E.g. "Right" (direction) vs. "Right" (entitlement).
    • Heteronyms: Words that are spelt the same but have a different sound and meaning. E.g. "desert" (leave) vs. "desert" (sahara) as in the above example.
    • Different Spelling: No technical word here, just words which mean and sound the same but are spelt differently. e.g. "Labor" (US spelling) vs. "Labour" (British Spelling).
    • Different Pronunciation: Again, no technical word, just two words which are written and mean the same, but sound different. E.g. 'the elephant' vs. 'the circus'.  ('the' takes a different sound in each).
    • Synonyms: Two words with the same meaning, but different pronunciations and written forms.  e.g. "friend" and "companion". Useful for lexical simplification as synonyms can be ranked according to their simplicity.
    • Same Word: No difference here whatsoever.
    So there you have it.  I hope this is a helpful contribution to the often confusing world of word relation nomenclature.  I am certainly much more clear on the distinction between these terms as a result of writing this blog.

    Wednesday, June 19, 2013

    The importance of being accurate.

    Only a short post today. I am currently writing my transfer report, which is soaking up all of my research time.  I thought I would take some time out from that to write about an interesting phenomenon that occurs in text simplification.

    Accuracy is always to be sought after.  Regardless of your domain, the more accurate your algorithm, the better.  In many domains, negative results can be tolerated.  For example, if you search for the query 'jaguar in the jungle' you are likely to receive lots of results about big cats in their natural habitat, but you may also receive some results about fancy cars in the jungle too.  This is acceptable and may even be helpful as the original query contained some ambiguity - maybe you really wanted to know about those fancy cars.

    The same thing can occur during text simplification.  Inaccurate identifications or replacements may lead to an incorrect result being present in the final text.  Some of the critical points of failure are as follows:
    • A complex word could be mislabeled as simple - meaning it is not considered for simplification.
    • No replacements may be available for an identified complex word.
    • A replacement which does not make sense in the context of the original word may be selected.
    • A complex replacement may be incorrectly selected over a simpler alternative due to the difficulty of estimating lexical complexity
    If any of the above pitfalls occur, then either a complex word or an erroneous replacement may creep into the final text.  Unlike in web search, errors are of great detriment to the simplification process.  This is because the point is to have text which is easier to understand.  In the majority of cases, introducing errors into a text will cause it to be more difficult, completely negating any simplification made.  This is a real case of one step forwards and two steps back.  For example:

    A young couple with children will need nearly 12 years to get enough money for a deposit.
    was changed by a rudimentary lexical simplification system to:

    A young couple with children will need nearly 12 years to get enough money for a sediment.
    Not only has a synonym which is more complicated than the original word been chosen here, the synonym does not make any sense in the given context.  Through making an error, the understandability of the text is reduced, and it would have been better to make no simplification at all.

    To end this post, I will present some practical ways to mitigate this.
    1. Only simplify if you're sure.  Thresholds for deciding whether to simplify should be set high to avoid errors.
    2. Use resources which are well suited to your task, preferably built from as large a corpus as possible.
    3. Investigate these errors in resultant text.  If they are occurring, is there a specific reason?
    In summary, incomprehensible text is much more complex than understandable yet unsimplified text.  Whilst the goal of text simplification must be to simplify when and wherever possible, this must not be done at the expense of a system's accuracy.  Presenting a reader with error prone text is as bad, if not worse than presenting them with complex text.

    Wednesday, May 29, 2013

    Identifying Complex Words

    The very first step in lexical simplification is to identify complex words (CWs).   This is the process of scanning a text and picking out the words which may cause a reader difficulty.  Getting this process right is important, as it is at the first stage in the simplification pipeline.  Hence, any errors incurred at this stage will propagate through the pipeline, resulting in user misunderstanding.

    How do we define a CW?

    In my previous blog post, I gave several factors that come together to form lexical complexity.  Lexical complexity values can be inferred, using the metrics given there.  Typically, word frequency is either used by itself, or combined with word length to give a continuous scale on which complexity may be measured.  We can then use this scale to define and identify our CWs as described below.

    How do we identify them?

    There are a few different methods in the literature for actually identifying CWs.  I have written a paper discussing and evaluating these which is referenced at the end of this section.  For now, I'll just give a brief overview of each technique - but please do see the paper for a more in depth analysis.
    1. The most common technique unsurprisingly requires the least effort.  It involves attempting to simplify every word and doing so where possible.  The drawback of this technique is that the CWs are never identified.  This means that difficult words which can't be simplified (e.g. beacuse there is no simpler alternative), won't be.  It also means that words which are not causing a barrier to understanding may be modified, potentially resulting in error.
    2. Lexical complexity (as explained above) can be used to determine which words are complex in a given sentence.  To do this, a threshold value must be established, which is used to indicate whether a word is complex.  Selecting a lexical complexity measure which discriminates well is very important here.  
    3. Machine learning may also be used to some effect.  Typically, Support Vector Machines (SVMs, a type of statistical classifier) have been employed for this task.  Lexical and syntactic features may be combined to give an adequate classifer for this task.
    I am soon to publish a comparison of the above techniques at the ACL-SRW 2013.  I will put a link up to that paper here when it is available.


    The CW corpus

    To compare different techniques in CW identification, it is necessary to have an annotated corpus.  My solution to this was to extract sentences from Simple Wikipedia edit histories which had been simplified by a revising editor.  I have a separate paper submitted on this and will write more about it in a future post.  The corpus contains 731 sentences, each with one annotated CW.  This can be used for fully automatic evaluation.  The data is available from the resources page.

    User-dependent complexity

    Complexity is a subjective measure and will vary from user group to user group and even from user to user.  For example, take the case of a class of English language learners.  They will all have different levels of English proficiency and will have differing knowledge of English, based on their experience of it to date.  A language learner who has been on holiday to England several times may have different simplification needs to a language learner who has watched many films in English, subtitled in their own language.  A language learner whose first language is Italian will find many words to be similar to their own language, similarly a learner whose first language is German may also find many words to be similar. However, German and Italian speakers will not find the same English words familiar.  It could even be hypothesised that words which an Italian speaker found simple, would need to simplified for a German speaker and vice versa.

    E.g.

      German               English                    Italian
    Verwaltung       Administration    Amministrazione
         Apfel                 Apple                       Mela

    The above toy example shows how one language learner's simplification needs may differ from another.  The German speaker will find the word 'Apple' familiar, yet struggle with 'Administration', the Italian speaker will experience the reverse.

    There is very little work on discerning the individual simplification needs of a user.  This is not just a problem confined to language learning (although it may be seen there very clearly) but it affects all spheres of text simplification.  A technique which could adapt to a user's needs, maybe incorporating feedback from a user where appropriate would go far.

    Friday, May 17, 2013

    Lexical Complexity

    Lexical simplification often requires some method of determining a word's complexity.  At first glance, this sounds like an easy task.  If I asked you to tell me which word is simpler: 'sit' or 'repose', you would probably tell me that the first was the easiest.  However, if I asked you to say why, it may be more difficult to explain.

    Many factors influence the complexity of a word.  In this post, I will identify six key factors, these are: Length, Morphology, Familiarity, Etymology, Ambiguity and Context.  These are not an exhaustive list, and I'm sure other factors contribute too.  I have also mentioned how to measure these where appropriate.

    1.  Length

    Word length, measured in either characters or syllables is a good indicator of complexity.  Longer words require the reader to do more work, as they must spend longer looking at the word and discerning it's meaning.  In the (toy) example above, sit is 3 characters and 1 syllable whereas repose is 6 characters and 2 syllables.

    Length may also affect the following two factors.

    2.  Morphology

    Longer words tend to be made up of many parts - something referred to as morphological complexity.  In English, many morphemes may be put together to create one word.  For example 'reposing' may be parsed as: re + pose + ing.  Here, three morphemes come together to give a single word, the semantics of which are influenced by each part.  Morphosemantics is outside the scope of this blog post (and probably this blog!) but lets just say that the more the reader understands about each part, the more they will understand the word itself.  Hence, the more parts there are, the more complex the word will be.

    3.  Familiarity

    The frequency with which we see a word is thought to be a large factor in determining lexical complexity.  We are less certain about the meaning of infrequent words,  so greater cognitive load is required to assure ourselves we have correctly understood a word in it's context.  In informal speech and writing (such as film dialogue or sending a text message) short words are usually chosen over longer words for efficiency.  This means that we are in contact more often with shorter words than we are with longer words and may explain in part the correlation between length and complexity.

    Familiarity is typically quantified by looking at a word's frequency of occurrence in some large corpus.  This was originally done for lexical simplification using kucera-francis frequency, which is frequency counts from the 1-million word Brown corpus.  In more recent times, frequency counts from larger corpora have been employed. In my research I employ SUBTLEX (a word frequency count of subtitles from over 8,000 films), as I have empirically found this to be a useful resource.

    4.  Etymology

    A word's origins and historical formations may contribute to it's complexity as meaning may be inferred from common roots.  For example, the latin word 'sanctus' (meaning holy) is at the etymological root of both the English words 'saint' and 'sanctified'.  If the meaning of one of these words is known, then the meaning of the other may be inferred on the basis of their 'sounds-like' relationship.

    In the above example, 'sit' is of Proto-Germanic Anglo Saxon origins whereas 'repose' is of Latin origin.  words of Latin and Greek origins are often associated with higher complexity.  This is due to a mixture of factors including the widespread influence of the Romans and the use of Latin as an academic language.

    To date, I have seen no lexical complexity measures that take into account a word's etymology.

    5.  Ambiguity

    Certain words have a high degree of ambiguity.  For example, the word 'bow' has a different meaning in each of the following sentences:

    The actors took a bow.
    The bow legged boy stood up.
    I hit a bull's eye with my new carbon fibre bow.
    The girl wore a bow in her hair.
    They stood at the bow of the boat.

    A reader must discern the correct interpretation from the context around a word. This can be measured empirically by looking at the number of dictionary definitions given for a word.  According to my dictionary, sit has 6 forms as a noun and a further 2 as a verb, whereas repose has 1 form as a noun and 2 forms as a verb.  Interestingly, sit is more complex by this measure. 

    6.  Context


    There is some evidence to show that context also affects complexity.  For example: take the following sentences:

    "The rain in Spain falls mainly on the ______"
    "Why did the chicken cross the ______"
    "To be or not to ___"
    "The cat ____ on the mat"

    In each of these sentences, you can easily guess the blank word (or failing that use Google's auto complete feature).  If we placed an unexpected word in the blank slot, then the sentence would require more effort from the reader.  Words in familiar contexts are more simple than words in unfamiliar contexts.  This indicates that a word's complexity is not a static notion, but is influenced by the words around it.  This can be modelled, using n-gram frequencies to check how likely a word is to co-occur with those words around it.

    Summary

    So, if we put those factors into a table it looks something like this:

    Word "sat" "repose"
    Length (characters) 3 6
    Length (syllables)12
    Familiarity (frequency)338329
    Morphology (morphemes) 1 2
    Etymology (origins) Proto-Germanic Latin
    Ambiguity (senses)83
    Context* (frequency) 6.976 0.112
    *source: Google n-grams value for query "the cat ____".  Value is percentage occurrence and is multiplied by a factor of 10^7

    We see that repose is more difficult in every respect except for the number of senses.

    Lexical complexity is a hard concept to work with, it is often subjective and shifts from sense to sense and context to context.  Any research into determining lexical complexity values must take into account the factors outlined here.  The most recent work into determining lexical complexity is the SemEval 2012 task in lexical simplification.  This is referenced below for further reading.

    L. Specia, S. K. Jauhar, and R. Mihalcea. Semeval-2012 task 1: English lexical simplification. In First Joint Conference on Lexical and Computational Semantics, 2012
    Wednesday, May 08, 2013

    Lexical Simplification: Background

    My PhD work is concerned with a process called lexical simplification.  I'm interested in how natural language processing can be applied to make documents easier to read for everyday users.  Lexical simplification specifically addresses the barriers to understandability provided by the difficult words in a text.

    For example, take the following sentence:

    The workers acquiesced to their boss' request.

    It is fairly clear that the rarely used verb 'acquiesce' is going to cause understandability issues here.  Do you know what it means?  Maybe in a wider context you could guess the meaning, however here it is fairly difficult to work out.  Lexical simplification deals with sentences such as the above and attempts to process them into more understandable forms.  There are several stages to the lexical simplification pipeline.  I intend to devote an entire post to each one of these as I continue, however for now, it should be sufficient to give an overview of each one.

    The first stage in any lexical simplification system is complex word identification.  There are 2 main approaches to this.  Firstly, systems will attempt to simplify every word and those for which simplifications can be found are transformed, those which cannot be transformed are left.  Secondly, some form of thresholding is applied.  There are various measures of lexical complexity - which often reside heavily in word frequency.  Some threshold may be applied to one of these measures to determine between complex and simple words.  One of the major issues in this field is the lack of evaluation resources.  I have a paper on this topic accepted at the ACL student session 2013,  so will write more at that time.

    If we assume that we can get lexical complexity values of:

    worker: 300
    acquiesce:    5
    boss: 250
    request: 450

    If we also assume that our threshold (which is set on some training data) is somewhere between 5 and 250 then we have an indicator that 'acquiesce' is a difficult word.

    The next step, once we have identified this complex word is to generate a set of synonyms which could replace it.  This is typically done with a thesaurus such as WordNet.  This could give us some of the following replacements for acquiesce.

    Acquiesce: accept, accommodate, adapt, agree, allow, cave in, comply, concur, conform, consent, give in, okay, submit, yield

    We must then process these to discover which will be valid replacements in the given context.  This third step is called word sense disambiguation.  This is necessary as a word will have typically have several senses, so some replacements will only be valid in certain contexts.  In the above example a word sense disambiguation step may look something like the following:

    Acquiesce: accept, accommodate, adapt, agree, allow, cave in, comply, concur, conform, consent, give in, okay, submit, yield

    Where words in green are those that would be valid replacements and words struck-through and in red are non-valid replacements.   This is somewhat subjective and remains an unsolved task in NLP.

    The final step is to rank the resulting replacements in order of their simplicity.  The simplest will then replace the original word.  To do this we revisit our measure of lexical complexity from before.  For example if we have the following values for the remaining candidates:

    accept:
    550
    agree:   
    450
    cave in:
    250
    comply
    35
    conform
    50
    give in
    350
    submit
    40
    yield
    20

     Then we would choose 'accept' as our replacement.  Giving the simplified sentence as:

    The workers accepted their boss' request.

    Which is a much more understandable sentence.

    There are of course some nuances of the original meaning that are lost in this simplification, however this has to be accepted.  The understandability of the sentence is obviously dramatically increased.

    My project is currently focusing on each of these stages individually.  The hypothesis is that by examining and optimising each stage in turn, it will be possible to improve the final simplification.  Work has already taken place in the first stages mentioned above and work will continue on the rest.

    There is much more to lexical simplification than the basic outline presented above and readers wishing to know more should look to read the following publications:


    Siobhan Devlin and John Tait. 1998. The use of a psycholinguistic database in the simplification of text for aphasic readers. Linguistic Databases, pages 161–173.


    Or Biran, Samuel Brody, and No ́emie Elhadad. 2011. Putting it simply: a context-aware approach to lexical simplification. In Proceedings of the 49th Annual Meeting of the Asso- ciation for Computational Linguistics: Human Language Technologies: short papers - Volume 2, HLT ’11, pages 496–501, Stroudsburg, PA, USA. Association for Computational Linguistics.


    Stefan Bott, Luz Rello, Biljana Drndarevic, and Horacio Saggion. 2012. Can spanish be simpler? lexsis: Lexical simplification for spanish. In COLING, pages 357–374. 


    S. M. Alu ́ısio and C. Gasperin. Fostering digital inclusion and accessibility: the PorSimples project for simplification of Portuguese texts. In Proceedings of the NAACL HLT 2010 Young Investigators Workshop on Computational Ap- proaches to Languages of the Americas, YIWCALA ’10, pages 46–53, Strouds- burg, PA, USA, 2010. Association for Computational Linguistics. 

    L. Feng. Text simplification: A survey, 2008.

    L. Specia, S. K. Jauhar, and R. Mihalcea. Semeval-2012 task 1: English lex- ical simplification. In First Joint Conference on Lexical and Computational Semantics, 2012.